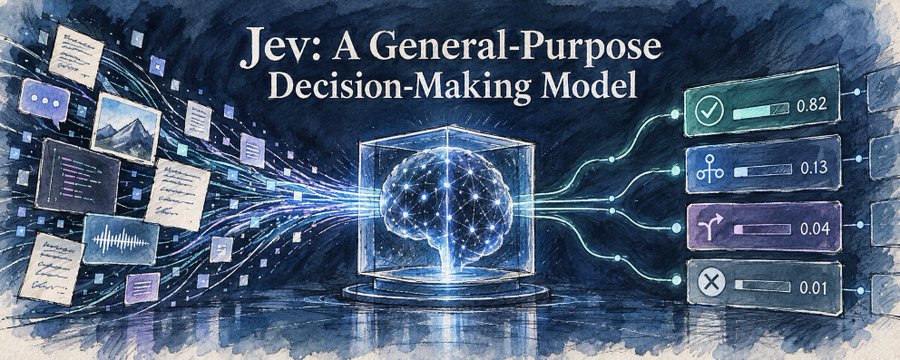
Unlike LLMs specialized for generating conversation, Jev is a general-purpose decision model designed to make judgments that include probabilities between a given situation and a set of options. TypeSafe aims to use it to sharply reduce the cost and latency of automation, but hands-on testing also revealed high-probability wrong answers, probability mismatches depending on how a question is phrased, and results that vary from call to call. Jev's core value, therefore, lies not in replacing every decision but in handling narrow, repetitive judgments quickly while being used inside a verification system made up of code and people.
1. The Question Jev Raises: Why Haven't Excellent Conversational Models Led to Automation?
Diogo Almeida, who built Jev, is introduced as a co-developer of ChatGPT, a contributor to OpenAI's InstructGPT research, and one of the authors of GPT-4. He was at the center of today's LLM wave, yet for roughly the past four years he has been wrestling with why LLMs have not been used enough for real-world automation.
The question he poses is simple.
"Models have long outperformed humans at conversation, so why is so little actual automation happening?"
Almeida's answer points less to the models' capabilities than to the wrong optimization target. Conventional RLHF, that is, tuning a model to give the answers people prefer, can push a model to produce answers that sound plausible and confident rather than answers that are factually correct.
In particular, reward models tend to rate the hesitation of "I'm not sure" worse than a confident wrong answer. The GPT-4 technical report also notes that the pretrained GPT-4's confidence closely matched its actual accuracy, but that this agreement deteriorated significantly after post-training. The article describes this in terms of ECE as follows.
- ECE of pretrained GPT-4: about 0.007
- ECE after post-training: about 0.074
In other words, if you can no longer trust that a model saying "I'm 95% confident" is actually right 95% of the time, it becomes hard to use for automation. Even if it gets 95% right, if it can't tell you which 5% will be wrong, a person ends up having to recheck every result.
2. A Critique of Existing LLM Automation Approaches
To put LLMs into real software, developers have bolted on various safeguards. Typical examples include structured output, enforced JSON schemas, parsers, retries, and guardrails.
Almeida, however, does not see these as fundamental fixes. Masking logits so a model cannot generate malformed tokens only blocks the visible symptom; if the model is assigning probability to wrong tokens in the first place, he argues, it is already internally confused.
Jev takes a different direction. Instead of fluently generating long passages, it focuses on judging which of the possible options fits a particular situation, and returning that judgment with a probability attached.
The name comes from the Jevons paradox. Just as coal consumption rose rather than fell as steam engines became more efficient, the name reflects the expectation that if the cost of using intelligence drops dramatically, the range of work AI can be applied to will expand. ⚙️
3. The Problem Jev Aims to Solve and Its Basic Interface
Real-world automation more often stalls on small judgments than on big ones. Consider questions like these:
- Is the customer actually requesting a refund, or just asking about the process?
- Is the retrieved document relevant to the current task?
- Is it okay to proceed to the next step now?
- What should the next action be in a game or browser?
People read the context and distinguish these naturally, but software needs something to hand such small judgments to. Existing LLMs can do it, but the article's view is that they are inefficient because they were never built for decision-making in the first place.
TypeSafe's Jev takes a situation (state), questions, and possible answers and judgment criteria (Choice) as input. It then returns the selected result and probabilities in a fixed format.
Distribution over answers = Jev(situation, questions, possible answers and judgment criteria)

When the task changes, you don't train a new model each time; you change the situation, questions, and option descriptions passed as input. For example, suppose a customer message reads:
"The shoes are too small, so please just tell me the exchange process. I'm not going to submit a request yet."
If you ask "What is the current intent?" about this sentence, the options could be process inquiry, exchange request, and request cancellation. If instead you ask "Which department should handle this?" and describe each department's role, the same customer message becomes a different decision problem.
The key point is that you don't just give the model bare labels; you also pass in the classification scheme to use for this call and the meaning of each option.
4. Zero-Shot Judgment and the RLCD Training Approach
Jev does not require multiple labeled examples or extra training for each new task. It handles new cases using only a task description and judgment criteria, an approach known as zero-shot.

This approach builds on the language understanding the model already has. It carries over to new tasks its ability to read intent from what people say, understand policy conditions, and connect the current situation to the options. Even when the task shifts from customer support to document evaluation, the model interprets the newly supplied questions and criteria and applies its existing capabilities.
TypeSafe explains that, during model development, it trained Jev on top of a pretrained language model using a method called RLCD.
- RLCD: Reinforcement Learning for Calibrated Decisions
- Meaning: a reinforcement learning method that trains the model so that its decisions, and the probabilities attached to them, match actual outcomes well
However, the specific training data, loss function, and internal architecture have not been disclosed. Users don't change the already-trained model weights; they only supply their own data and judgment criteria. TypeSafe states that it does no per-customer additional training and does not use requests and responses for training.
In multi-step tasks, the results of earlier judgments can be placed into the state of the next request. But storing history, selecting the necessary information, and assembling it into the next input are handled by the surrounding system, not by Jev.
5. Hands-On Results: Strong Performance on Short Language Judgments
To test Jev's generality, the article ran a small experiment using fictional customer inquiries and online store order records. All data was newly created fictional data for this evaluation, and rather than treating another model's answers as ground truth, the correct answers were set by hand in advance.
The test was structured as follows:
- 100 judgments in total, asking 5 questions per case across 10 Korean and 10 English sentences
- A test on 8 fictional refund cases, passing in the raw records and a code-organized state for each
- Speed tests that repeated identical inputs or varied the number of questions among 1, 4, and 16
Every call used a distinct request ID, and the responding model version was jev-1.13.0 in all cases.
On short language judgments, it got all 100 judgments right, 50 in Korean and 50 in English. In particular, it correctly distinguished negations and conditionals that could trip up simple keyword matching.
For example, the model handled distinctions such as:
- "I'm not asking for a refund"
- "That doesn't mean I don't want a refund"
- A case where a previously requested refund was canceled
- A future conditional request: "If this isn't resolved by tomorrow, I'll request a refund then"
- An information inquiry: "Just tell me the refund process"
- An underspecified expression like "Please take care of that"
Notably, it classified sentences like the last one, which lack grounds for a judgment, as unknown in both Korean and English. That said, this result came from a setup where unknown was provided as an option in the first place.
The article is careful to say that this score alone does not justify concluding that "it is good enough for real-world Korean workloads." In practice there were only ten independent meanings, and real-world complications such as typos, long conversations, and domain jargon were not included.
6. The Importance of Input Design, Revealed in a Compound Refund Task
Deciding whether to approve a refund is harder than simply identifying the intent of a sentence. Beyond checking whether the customer requested a refund, you have to link order records and calculate dates and amounts.
The fictional refund policy was set to approve only when all four of the following conditions are met:
- The customer is currently requesting a refund
- It is within 30 days of receiving the product
- Exactly day 30 is also allowed
- The product is unopened
- The balance, i.e. the amount paid minus the amount already refunded, is greater than 0 won
The input included three orders, invoices, payment records, and multiple refund records, and some records for other orders unrelated to the current case were mixed in.

In the first comparison, the question wording and number of questions differed, making the comparison imperfect, so the article ran an additional experiment using a single identical Choice question. The results were:
- Raw record input: 5 of 8 correct
- Code-organized state input: 8 of 8 correct
The organized input totaled 4,599 tokens, versus 8,543 for the raw records. In other words, the organized input was about 46.2% shorter and still produced better results.
The article does not, however, interpret this simply as "it improved because there were fewer tokens." State length, information structure, and whether code did the calculations all changed at once, so it is hard to isolate which factor had the biggest effect.
The practical lesson of this test is clear: let code handle first what code can reliably do, such as date calculations, amount calculations, and data linking, and leave Jev with narrow semantic judgments.
7. Three Refund Judgments It Actually Got Wrong
In the compound refund test, there were also three cases Jev got wrong. They show that returning probabilities does not mean Jev's judgments are always accurate or logically consistent.
An order one day past the return window
The first case was an order where 31 days had passed since receipt. Under the policy, only orders within 30 days are refundable, so rejection is correct.
Yet Jev initially returned a final approval probability of 80%. Within the same request, for the individual question "Is it within 30 days?", it answered with a 34% probability that the condition was met. Combining the individual conditions yields rejection, yet the final conclusion came out as approval.
A controlled experiment with fixed question wording produced the following:
- Approval probability: 92%
- confidence: 0.85
- Repeated calls with the same input: approval probability 88%, 89%
In other words, it was not mere chance; the same wrong judgment repeated.
An order already fully refunded
The second case was an order with a payment of 129,900 won, with 69,900 won and 60,000 won already refunded, leaving a balance of exactly 0 won. Since no money remains to be refunded, it should be rejected.
Jev, however, judged the probability that the balance was positive at 76%, and chose final approval at 67%. Even with the questions broken down further, the error persisted when the model got the amount calculation wrong.
By contrast, when code calculated the balance and put the fact "the balance is 0 won" directly into the state, the result changed to rejection. This illustrates well why calculation-type judgments should not be left entirely to the model.
An order at exactly 30 days
The third case was an order exactly 30 days after receipt, which the policy allows.
On the individual questions, the probabilities of the conditions being met came out relatively high:
- Currently requesting a refund: 90%
- Within the time window: 93%
- Unopened: 97%
- Positive balance: 83%
Yet on the final question, rejection at 58% was chosen instead. Combining the individual conditions in code yields approval, but the model reached the opposite conclusion in its overall judgment.
This means you cannot assume that multiple answers produced in parallel automatically form a single, logically consistent system.
8. Probability, Confidence, and Repeatability: Cautions for Automation Rules

Jev typically returns the selected result, a probability for each option, and a separate confidence value together.
choice: "approve"
probabilities: { approve: 0.92, reject: 0.06, hold: 0.02 }
confidence: 0.85
The article explains that there are three things to watch out for when using these numbers as branching conditions in automation.
A high probability does not guarantee a correct answer
The order 31 days past receipt clearly should have been rejected, yet Jev assigned 0.92 to approval. If the system had used a rule like "auto-approve without human review when the approval probability exceeds 0.9," this wrong answer would have gone straight through.
That said, a single high-probability wrong answer is not enough to conclude that Jev's probability calibration has failed. For example, to see whether answers labeled 0.9 are actually correct 90% of the time, you would need to collect hundreds or more cases in that range and compare against the actual accuracy.
Also, confidence is separate from the option probabilities. Option probabilities are values attached to each answer, while confidence is a figure summarizing how strongly the overall probability distribution leans in one direction. So the outcome depends on which value you apply a threshold like "auto-process at 0.9 or above" to.
Positive and negative questions do not complement each other
Suppose you ask the following two questions separately about the same sentence:
- "Are they currently requesting a refund?" → 0.63
- "Are they currently not requesting a refund?" → 0.07
Flipping the second answer means a 0.93 probability that they are requesting a refund. So even though the same fact was asked about, you get two different values: 0.63 and 0.93. The fact that the two values sum to 0.70 rather than 1 exposes the problem.
Jev scores each question independently and does not reconcile multiple answers into a single consistent probability system. So you should not simply add or subtract the probabilities of opposite questions. If you need the opposite probability, it is safer to ask in only one direction and subtract from 1 in code.
The same input yields slightly different results
When the same sentence was sent three times, the probability varied slightly: 0.63, 0.64, 0.65. The wrong approval probability for the fully refunded order swung more widely, at 0.60, 0.65, and 0.78.
In this test, the choice itself never flipped, but for cases near a threshold this becomes a problem. If the auto-processing threshold is 0.7 and results bounce between 0.69 and 0.71, the same request might sometimes be auto-processed and sometimes be sent to human review.
You therefore need a mechanism such as routing ambiguous probability ranges to human review from the start, or holding a decision for a set period once it is made.
"Which numbers to use with which thresholds, and how to handle ambiguous ranges, must be decided outside the model and verified yourself."
9. Speed and Cost: The Advantage of Asking Multiple Judgments at Once

The server processing time across 68 calls in total was:
- Median: 113.6ms
- 95th percentile: 484.3ms
- Minimum: 62.9ms
- Maximum: 1,263.8ms
These values were measured based on evaluation_time_ms in the responses. The median network time shown on screen was about 566ms, and the median of the two combined was about 672ms. However, since the network time is a rounded figure from the screen, it is hard to treat this as a rigorous end-to-end measurement.
A speed experiment that varied only the number of questions on the same state was also run:
- 1 question: 87.4ms
- 4 questions: 106.4ms
- 16 questions: 113.5ms
Each condition was run three times in shuffled order. Because latency did not increase proportionally even when the number of questions grew 16-fold, an advantage of requesting multiple judgments at once was observed. Still, with only three samples per condition, the result cannot be generalized to heavy load or long-document settings.
Total input was 52,974 tokens. Applying the published price of $0.042 per million input tokens gives roughly 0.22 cents, and the 5,577 output tokens are free under that pricing plan. However, this is only an estimate calculated from published rates and usage, not a figure verified against an actual invoice.
Because the article did not compare other models under the same conditions, it does not present any figures claiming Jev is some multiple faster or cheaper.
10. Real-World Use Cases and the Constraints of Options
Jev's public use cases fall into three broad directions:
- Choosing the next action in games and browsers
- Evaluating documents and code against multiple criteria
- Checking the output of generative models and deciding the next processing path
In each case, the surrounding program prepares the state and candidate actions and connects Jev's judgment to actual execution. Such an execution framework is often called a harness. So when looking at demos, you need to distinguish between the judgments Jev itself made and the functionality the harness provided.
The public community list is described as having 133 builds and 45 guides as of September 18, with the most examples in agents, browsers, tools, apps, games, and real-time, in that order.

Jev's action space is constructed at runtime. "Defining options in advance" does not mean fixing every candidate at development time. It means that right before the call, the program generates candidates that fit the current situation and includes them in the request.
In chess, code generates the legal moves available on the current board; in a browser agent, it extracts the interactable elements from the DOM. In customer support, the list of departments registered in the system can be passed as options.
"The side that generates the candidates is always code."
Because Jev cannot generate text, it cannot invent actions that don't exist. Instead, it scores each candidate it receives and picks one. This is both a constraint and a strength. Since it cannot take actions outside the candidate set, the risk of choosing a button that isn't on screen or a chess move that doesn't exist also goes down.
However, a single Choice can hold at most 255 candidates. Continuous values such as a steering angle, and new actions not on the candidate list, are hard to handle. When there are many candidates, as in wiki navigation with thousands of links, you need a two-stage approach: first score and narrow down the candidates, then choose again.
In TypeSafe's insurance claim example, sending the same request 15 times caused the coverage probability to fluctuate between 0.43 and 0.53. Under a rule that auto-approves anything above 0.5, the same claim could be approved on some calls and rejected on others.
That example therefore recommends, rather than cutting at a single boundary, leaving the 0.30–0.70 range as a zone for human review.
11. Division of Roles Between Jev and Agentic Frameworks
Jev makes just one judgment about the current moment per call. Chaining multiple judgments to complete long-running work requires a separate system, generally called an agentic framework.
The agentic framework takes on the following:
- Remembering the goal and the state of the work in progress
- Collecting the necessary facts and conversation history
- Organizing the latest information into Jev's input
- Composing the questions and options for the current step
- Turning Jev's answers into actual actions
- Reflecting execution results in the next state

The most practical structure divided the roles as follows:
- The framework maintains order information and conversation history.
- Code calculates facts that can be computed unambiguously, such as dates, amounts, and refund balances.
- Jev makes narrow semantic judgments, such as whether a customer's utterance is a refund request, a cancellation, or a process inquiry.
- Code does the final check on policy conditions and execution permissions.
- The result is recorded in the state and, if needed, passed on to the next judgment.
In this structure, Jev can in some cases become part of the policy, because it produces a distribution over permitted actions based on the current observation, goal, and history. Conversely, in tasks such as grading writing or checking for errors, it plays the role of an evaluator.
The important point is that Jev handles short-horizon judgments. Whether it is a single next click in a browser or a short bundle of robot motions, the time scale differs, but each is part of the actions taken toward a larger goal. To carry out long-horizon tasks, goal management, state updates, action execution, and feedback handling must continue to happen outside Jev.
12. Closing: Jev Is Not an All-Purpose Decision Maker but a Decision Component
The reason Jev can be called a general-purpose decision model is that it takes as input not just the situation but also the judgment criteria and the permitted options. Give it a customer request and classification criteria, and it classifies the inquiry; give it the current web page and the interactable elements, and it can choose the next action.
Being able to apply understanding gained from pretraining to the current situation and criteria, without training a new model for each task, is a clear advantage. Ultimately, attaching Jev to real work is less about retraining a model and more about designing the following:
- What to show as state
- What to ask
- Which options to allow
- Which results to process automatically, and where to hand off to people
But as the article stresses, Jev has not solved the decision-making problem itself. In testing, high-probability wrong answers, logical inconsistencies, probability differences depending on question phrasing, and result variation for identical inputs actually appeared.
"Jev's value is in making decisions cheap and fast."
So Jev does not immediately solve problems like computer use or high-risk autonomous systems such as self-driving. Where it clearly fits today is decision work that has narrow options, high repetition volume, and a verification system of code and people in place.
Even if Jev becomes more accurate, the importance of the surrounding system that decides what to show and which candidates to create will not disappear. In the end, Jev is best understood not as an intelligence that replaces everything, but as a decision-making component that delivers fast, cheap judgments within a well-designed system.